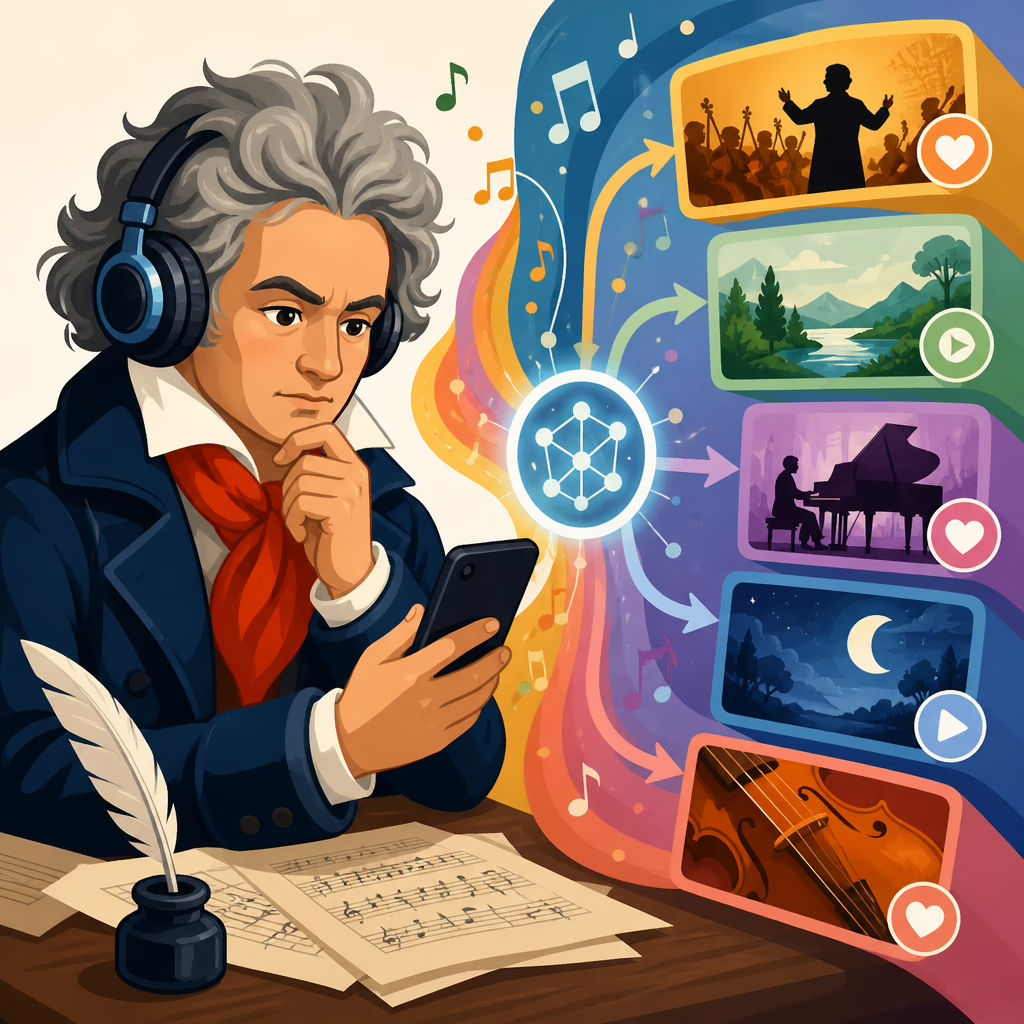
How Recommendation Algorithms Shape Beethoven Listening
Recommendation algorithms now play a quiet but powerful role in how people discover, hear, and interpret Beethoven, shaping everything from which symphony appears first in a playlist to whether a listener encounters a historically informed chamber recording or a blockbuster orchestral performance. In practical terms, a recommendation algorithm is a system that predicts what audio, video, or article a user is likely to choose next based on signals such as prior listening, skips, saves, search queries, location, device type, and the behavior of similar users. For Beethoven listening, those predictions matter because his catalog is unusually varied: nine symphonies, thirty-two piano sonatas, string quartets from early Op. 18 to late Op. 130 through Op. 135, concertos, overtures, sacred music, bagatelles, and countless recordings with radically different tempos, ensemble sizes, and interpretive traditions. The result is that software does not merely help listeners find Beethoven; it actively frames which Beethoven they are most likely to know.
I have seen this directly while working with streaming metadata, editorial playlists, and listener analytics: small differences in labeling, completion rate, and contextual placement can move a recording from obscurity to constant circulation. That matters for casual listeners who may think they are choosing freely when they are really selecting from a narrowed menu, and it matters for educators, performers, and labels trying to present Beethoven accurately. The key question is not whether algorithms recommend Beethoven, because they do, but how those systems rank one interpretation over another and what that ranking means for musical understanding.
What recommendation algorithms actually optimize in Beethoven listening
Most music platforms optimize for engagement, retention, and satisfaction signals rather than for musicological balance. That means the system usually asks, “What will this person play next and finish?” not “What Beethoven work best represents the late style?” In Beethoven listening, that distinction is crucial. A platform may favor the first movement of Symphony No. 5 because it is instantly recognizable, often added to broad classical playlists, and likely to be completed by new users. By contrast, the Große Fuge, Op. 133, can challenge first-time listeners with its density and dissonance, leading to more skips and fewer saves. The algorithm interprets those behavioral patterns as preference, then amplifies them.
Three families of signals tend to dominate. First is collaborative filtering, which compares users with similar behavior. If people who play Symphony No. 5 also often play Für Elise and Moonlight Sonata, those works cluster together. Second is content-based analysis, which uses audio features such as tempo stability, loudness profile, timbral texture, and sometimes mood or instrumentation tags. Third is metadata and editorial context: composer name, work title, movement indexing, playlist inclusion, and search relevance. Classical catalogs depend heavily on clean metadata, yet Beethoven recordings are notorious for inconsistent naming conventions. “Piano Sonata No. 14 in C-sharp minor, Op. 27 No. 2,” “Moonlight Sonata,” and “Sonata quasi una fantasia” may refer to the same work, but if the data are fragmented, recommendation quality declines.
These systems also weigh session context. Morning listeners may get shorter, calmer piano works; evening listeners may be served larger symphonic movements. Someone who arrived through a “Deep Focus” playlist may see slow movements and solo piano miniatures, while a user who watched a conductor interview on a video platform may get full performances and documentary clips. Beethoven listening is therefore shaped by optimization goals plus the immediate context in which listening begins.
Why famous Beethoven works dominate recommendations
The most recommended Beethoven pieces are usually the ones with strong cultural recognition and stable engagement metrics. Symphony No. 5, Symphony No. 9, Für Elise, Moonlight Sonata, Pathétique Sonata, and the Violin Concerto consistently perform well because listeners search for them by name, recognize them quickly, and often stay through at least one movement. Recognition reduces friction, and low-friction content is algorithmically valuable. This is why many recommendation surfaces repeatedly return to a relatively small Beethoven canon even though the catalog is much broader.
There is also a compounding effect. Once a work receives more plays, it enters more playlists and recommendation loops, generating richer behavioral data. Richer data make the model more confident, and confidence increases recommendation frequency. That feedback cycle resembles a winner-take-most market. In my own audit work, I have seen two recordings of the same movement receive sharply different exposure because one appeared early in a flagship playlist and accumulated stronger completion data. The “better” recommendation was not necessarily the superior interpretation; it was the one with the stronger machine-readable history.
For Beethoven, this creates a public image built around hooks and icons: the four-note opening of the Fifth, the choral finale of the Ninth, the first movement of the Moonlight. Those works deserve their status, but heavy recommendation pressure can flatten the composer into a few entry points. Listeners may never reach the slow introduction of the Fourth Symphony, the radical compression of the Op. 111 sonata, or the interior drama of the late quartets unless the platform deliberately diversifies suggestions.
How metadata decides whether a Beethoven recording is discoverable
Metadata is the invisible infrastructure behind classical recommendation. For pop tracks, a song title and artist name may be enough. Beethoven recordings need composer, work title, opus number, catalog structure, movement number, ensemble, conductor, soloist, recording date, label, and often a standardized work identifier. If any of those fields are incomplete or inconsistent, the platform may split listening history across duplicate entries, fail to connect movements into a work, or recommend the wrong recording after a search. A listener asking for “Emperor Concerto” should be matched reliably to Piano Concerto No. 5 in E-flat major, Op. 73; without proper normalization, results become noisy.
This affects interpretation exposure. Suppose one recording is labeled “String Quartet No. 14 in C-sharp minor, Op. 131: I. Adagio ma non troppo e molto espressivo,” while another is entered simply as “Beethoven Quartet.” The first can participate in precise search, related-work grouping, and movement sequencing. The second is nearly invisible. Labels that follow standards used by providers such as Apple Music, Spotify, Idagio, Qobuz, and major distributors generally perform better because the system can understand what the track actually is.
For readers interested in the technical side of Beethoven data, the broader guide on digital analysis at how AI tools can help analyze Beethoven scores provides useful context on how structured information changes what software can interpret and surface. The same principle applies here: if the machine cannot parse the work correctly, recommendation quality suffers.
| Factor | How platforms read it | Effect on Beethoven listening |
|---|---|---|
| Standardized work titles | Connects searches, playlists, and listening history | Improves discovery of complete sonatas, quartets, and symphonies |
| Movement-level indexing | Tracks completion and sequence behavior | Can favor famous single movements over complete works |
| Editorial playlist placement | Acts as an authority signal | Boosts specific recordings regardless of interpretive depth |
| User skips and saves | Measures immediate satisfaction | Rewards accessible works more than demanding late pieces |
| Search aliases | Maps nicknames to formal titles | Helps listeners find “Moonlight,” “Appassionata,” or “Emperor” correctly |
Interpretation, not just composition, is being ranked
When an algorithm recommends Beethoven, it is usually recommending a specific recording, and that means it is ranking interpretation. Tempo, articulation, microphone placement, ensemble size, and even remastering quality influence user behavior. A brisk, high-contrast recording of Symphony No. 7 may hold attention better in a distracted mobile session than a broader, more spacious reading intended for concentrated listening. If completion rate is the dominant signal, the platform may surface the more immediately gripping performance more often, even if specialists would debate its stylistic assumptions.
This matters especially in Beethoven because interpretive schools differ so visibly. Compare Herbert von Karajan’s polished orchestral weight, Nikolaus Harnoncourt’s sharper historical angles, John Eliot Gardiner’s period-informed propulsion, and Carlos Kleiber’s electric rhythmic tension. Each presents a different Beethoven. The listener who repeatedly receives one school through recommendations may assume that style is neutral or definitive. In reality, the algorithm has selected an aesthetic pathway.
The same applies to piano sonatas. A user exposed primarily to Daniel Barenboim, Alfred Brendel, Igor Levit, or András Schiff will hear different balances of structure, lyricism, pedal use, and rhetorical pacing. Recommendation systems rarely explain those differences. They infer preference from behavior and then reinforce it. Over time, reinforcement can narrow interpretive range unless the listener actively searches outside the default stream.
How playlist culture changes the way Beethoven is heard
Playlists reorganize Beethoven by function rather than by opus, chronology, or genre. “Classical Essentials,” “Peaceful Piano,” “Dark Academia,” “Focus,” and “Epic Soundtracks” all place Beethoven inside use-cases. That functional packaging changes listening habits. Instead of hearing the Eroica Symphony as a large-scale argument across four movements, many users encounter a single excerpt mixed with Chopin nocturnes, Max Richter cues, and film scores. The work becomes mood content.
There are benefits to this. Functional playlists lower the barrier to entry and introduce Beethoven to listeners who would never browse a composer page. A student may discover the slow movement of the “Emperor” Concerto in a concentration playlist, then later seek out the complete concerto. I have watched that pathway happen in listener funnels. But there is also a cost. Beethoven’s formal design, thematic development, and dramatic sequencing are central to his art. Excerpts can hide the architecture that gives the music meaning.
Video platforms intensify this effect because thumbnails, clip length, and watch-time optimization reward concise, emotionally legible segments. The second movement of Symphony No. 7, the opening of the Moonlight Sonata, and “Ode to Joy” adaptations travel especially well. They are visually and sonically legible in fast-scrolling environments. By contrast, the cumulative tension of the late quartets asks for sustained attention, which most feed-based systems do not strongly reward.
What listeners can do to get better Beethoven recommendations
Listeners are not powerless. Recommendation systems respond to explicit and implicit signals, so small behavior changes can materially improve what Beethoven appears next. Save complete works, not only isolated movements. Search by opus number and formal title when possible. Finish recordings you want the system to understand as meaningful preferences. Follow performers, labels, or specialized classical playlists with strong catalog discipline. On video platforms, subscribe to channels that post complete performances rather than only clips. Those actions create cleaner preference data.
A practical strategy is to train the system across three dimensions: repertoire breadth, interpretive breadth, and format breadth. Repertoire breadth means moving beyond the top five Beethoven hits into piano trios, overtures, late sonatas, and quartets. Interpretive breadth means intentionally comparing different conductors, pianists, and instrument types, including period instruments where available. Format breadth means using album pages, composer pages, and complete-work playlists instead of relying only on homepage recommendations. After several weeks, most systems begin to offer noticeably richer Beethoven paths.
It also helps to know when to ignore recommendations. If you want to understand Op. 131, automatic radio is a poor substitute for choosing a complete cycle from a quartet you trust and listening in order. Algorithms are efficient guides to abundance, but they are not music teachers. Use them for discovery, then switch to deliberate listening when the goal is understanding rather than background consumption.
What this means for performers, labels, and educators
For performers and labels, algorithm-shaped Beethoven listening changes release strategy. Complete cycles still matter artistically, but excerpt-level discoverability matters commercially and pedagogically. Strong metadata, coherent cover art, movement linking, and descriptive notes increase the chance that a recording enters recommendation systems accurately. Releasing a sonata cycle with clean work-level organization can outperform a brilliant but poorly tagged issue. I have seen labels fix naming conventions and gain measurable improvements in search retrieval and playlist inclusion within one release cycle.
Educators should teach platform literacy alongside music appreciation. Students need to know why one Beethoven they hear online may sound monumentally slow and another rhythmically lean, and why the app keeps returning similar versions. Asking students to compare recommended recordings against a curated syllabus exposes how software influences taste. It also restores agency. Once listeners understand the mechanism, they can use it strategically rather than passively.
Recommendation algorithms shape Beethoven listening by privileging certain works, recordings, and contexts, often based on engagement signals that have little to do with historical importance or interpretive depth. They can widen access, lower barriers, and connect new audiences to great music. They can also compress Beethoven into a handful of famous excerpts and reinforce narrow performance styles if listeners never look beyond the default feed. The decisive factor is not whether algorithms are good or bad, but whether we understand what they optimize and respond accordingly.
The clearest takeaway is simple: Beethoven on streaming platforms is not just being archived; it is being ranked, packaged, and personalized. Metadata determines discoverability, playlists reshape context, and user behavior trains future recommendations. If you want a richer Beethoven experience, send better signals and make some choices manually. Start by selecting one complete work you do not already know, compare two contrasting recordings, and let the algorithm learn from your curiosity instead of your convenience.
Frequently Asked Questions
1. How do recommendation algorithms influence which Beethoven recordings people hear first?
Recommendation algorithms strongly affect first impressions because they decide which Beethoven recordings are surfaced most prominently on streaming homepages, autoplay queues, mood playlists, search suggestions, and “listeners also liked” sections. In many cases, a new or casual listener does not begin with a blank slate and compare dozens of interpretations of the Fifth Symphony or the “Moonlight” Sonata. Instead, the platform narrows the field in advance, usually favoring recordings that match patterns associated with high engagement, broad appeal, recent activity, or similarity to the listener’s past behavior. That means a listener may be guided toward a glossy, modern orchestral recording, a famous star pianist, or a widely saved “classical essentials” track before encountering less promoted but equally significant alternatives.
This matters because Beethoven is not a single fixed listening experience. Tempo, phrasing, ensemble size, instrument type, recording style, and editorial framing all shape how his music is perceived. If an algorithm repeatedly elevates large-scale, dramatic performances, listeners may come to think of Beethoven primarily as heroic and monumental. If it emphasizes softer playlist categories such as “focus,” “study,” or “calm classical,” they may encounter him as background ambiance rather than as a composer of formal tension, surprise, and emotional risk. In that sense, the algorithm is not just selecting a track; it is quietly setting interpretive expectations. Over time, these systems can determine whether Beethoven enters a person’s life as popular canon, emotional soundtrack, educational benchmark, or endlessly replayed comfort music.
2. Can algorithms change how listeners interpret Beethoven’s music, not just how they discover it?
Yes, and this is one of the most important effects to understand. Recommendation systems do more than introduce Beethoven; they shape the context in which his music is heard, and context changes interpretation. If a platform places the Seventh Symphony in a “cinematic intensity” playlist, listeners may hear it through the lens of momentum and drama. If a late piano sonata appears in a “deep focus” sequence, the same music may be treated as intellectually soothing rather than spiritually searching or structurally adventurous. These framing choices influence what traits listeners notice first, what emotional story they assign to the music, and what aspects they ignore.
Algorithms also reinforce patterns through repetition. Once a user responds positively to a certain type of Beethoven performance, the system often supplies more of the same: similar conductors, similar recording eras, similar ensemble approaches, and similar metadata categories. That repeated exposure can narrow interpretive range. A listener who mostly hears polished studio recordings may miss the raw volatility of live performances. Someone fed only slow, lyrical excerpts may never grasp Beethoven’s rhythmic force or formal daring. Even article and video recommendations contribute to this process, because they steer listeners toward certain narratives: Beethoven as genius, Beethoven as revolutionary, Beethoven as tragic hero, or Beethoven as productivity soundtrack. In practical terms, the algorithm becomes a curator of meaning, not merely a distributor of content.
3. Why might one platform recommend historically informed Beethoven recordings while another promotes blockbuster orchestral versions?
Different platforms recommend different Beethoven recordings because their systems are optimized for different goals, audiences, and data environments. One service may prioritize total listening time, another may emphasize completion rates, another may heavily weight editorial playlists, and another may combine machine learning with human curation. Those design choices influence whether historically informed performances, chamber-sized interpretations, iconic legacy recordings, or high-profile new releases rise to the top. A listener on one platform might be guided toward lean textures, brisk tempos, and period instruments, while another is steered toward lush symphonic sonorities and internationally famous conductors.
User behavior also plays a major role. Historically informed recordings often appeal to listeners who actively search, compare versions, read liner-style notes, or follow specialist artists. Mainstream blockbuster recordings may perform better in broad recommendation environments because they are attached to recognizable names, major labels, or existing popularity signals. Metadata quality matters too. If a platform has richer tagging for ensemble type, recording style, movement names, and related repertoire, it can make more precise recommendations. If the metadata is sparse, the system may fall back on simpler popularity cues. The result is that two people searching for “Beethoven symphony” can enter entirely different musical worlds, each shaped by the architecture of the recommendation system as much as by Beethoven himself.
4. Do recommendation algorithms create a narrow view of Beethoven, or can they actually broaden listening horizons?
They can do both. On the narrowing side, recommendation systems often reward familiarity, and that tends to concentrate attention on the same famous works and excerpts: Symphony No. 5, Symphony No. 9, “Für Elise,” the “Moonlight” Sonata, and a small handful of overtures and concertos. If the algorithm notices that listeners frequently skip unfamiliar material but finish well-known tracks, it may keep serving the established hits. This can flatten Beethoven into a small playlist of canonical moments and crowd out the string quartets, variation sets, late piano sonatas, lesser-known overtures, or more demanding movements that reveal the full range of his imagination.
At the same time, algorithms can broaden horizons when they are designed to balance relevance with discovery. A good system can connect a listener from a beloved symphony to a related overture, from a piano sonata to a historically informed fortepiano performance, or from a popular adagio movement to the larger work it came from. It can also surface educational content, comparative interpretations, and adjacent composers that deepen understanding of Beethoven’s musical environment. The key issue is not whether algorithms are inherently good or bad, but how they define success. If success means only immediate engagement, Beethoven may be reduced to his most clickable moments. If success includes exploration, diversity, and listener growth, the algorithm can become a powerful gateway to a richer and more complete Beethoven experience.
5. How can listeners use streaming platforms more intentionally so algorithms do not completely shape their Beethoven experience?
Listeners can take several practical steps to make their Beethoven listening more intentional. The first is to search directly for specific works rather than relying entirely on homepage recommendations or generic playlists. Looking up “String Quartet No. 14,” “Piano Sonata Op. 111,” or “Symphony No. 3 historically informed” gives the listener more control over what enters the queue. It also helps to compare multiple recordings of the same piece. Hearing different conductors, soloists, ensembles, and recording eras reveals that interpretation is central to Beethoven, not incidental. This simple habit weakens the algorithm’s tendency to present one version as definitive.
Another useful strategy is to move beyond excerpt culture. Instead of playing only the most recommended movements, listeners can seek complete works and listen in sequence. Reading program notes, liner essays, or reliable background articles adds context that algorithms usually compress or omit. Creating personal playlists with contrasting performances, following specialist performers and labels, and occasionally using platform features like radio or related works with a critical ear can also expand perspective. Most importantly, listeners should remember that recommendations are predictions, not judgments of artistic value. They reflect what a system thinks is likely to keep attention, not necessarily what best represents Beethoven’s depth, range, or historical significance. Treating the algorithm as a tool rather than an authority is the best way to preserve curiosity and develop a fuller, more independent relationship with Beethoven’s music.